
NVIDIA Nemotron 3.5 Transcribe and Granary v2, Reviewed by MyTechDailyNews Software: One Promptable Open Model for Multilingual Audio
Most teams already own a transcript and still cannot answer the follow-up questions: who talked over whom in the stand-up, what was actually agreed, and how to hand the Tokyo client call to the US desk in English with invoice amounts and drug names written the way your style guide demands. That gap between raw words and usable text is what this release targets. From a software-selection point of view the interesting part is that it ships as one open-weight checkpoint you can prompt, inspect and fine-tune — and the data recipe behind it is published too.
What ships in the release
Published on Hugging Face and ModelScope, NVIDIA Nemotron 3.5 Transcribe combines transcription, speaker attribution (diarization), translation and audio question answering in a single checkpoint. It transcribes 40 languages, translates 31 of them to or from English, and attributes speakers in 13. Long recordings are handled up to an hour, and up to eight speakers can be labeled. Because you choose the checkpoint and the serving stack, you also choose where the audio is processed — a practical privacy and compliance lever for anyone handling client calls, clinical dictation or classroom recordings.
Quantized versions are coming soon, which is when local use on RTX Spark, DGX Spark or Jetson AGX Thor — and larger rollouts on Blackwell data-center GPUs — enters the plan. Today the released checkpoint can be served with vLLM, and local deployment with NeMo-Speech.cpp is expected alongside those quantized builds. Two constraints belong in your evaluation checklist before you prototype anything: the model is built for recorded audio, not live streaming, and language support differs by task, so treat the model card's task-by-language matrix as the contract.
Capability matrix: match the task before you adopt
| Task | Coverage as released | What to verify in your own audio |
|---|---|---|
| Transcription | 40 languages | Names, product terms, digits and spelling conventions |
| Translation | 31 of the supported languages to or from English | Whether your language pair appears in the matrix |
| Speaker attribution | 13 languages, up to eight speakers | Overlap density; interviews and classrooms stress this hardest |
| Long recordings | up to an hour per session | Whether meetings exceed that and need splitting |
| Audio question answering | Trained in English | Phrase questions accordingly and spot-check every answer |
| Alignment detail | Word-level timestamps supported | Replay-synced captions, search and lecture review |
| Local and edge use | Quantized versions coming soon | Capacity planning on RTX Spark, DGX Spark, Jetson AGX Thor or Blackwell GPUs |
Who should adopt now, and who should wait
- Multilingual archives and global support calls: adopt now — one recording can yield verbatim text, an English translation, speaker labels and a Q&A summary without stitching separate tools.
- Meeting-notes and media teams: adopt now for overlap-heavy audio; the diarization results below are the reason to run a test.
- Clinical, legal and field-terminology workflows: start with prompt presets, then budget fine-tuning — the medical case study quantifies the difference.
- Live captioning or real-time voice agents: wait, because this checkpoint is built for recorded audio.
- Teams under strict data-residency rules: self-host with vLLM today; edge options arrive with the quantized versions.
Prompt it before you retrain it
One checkpoint can produce different outputs from the same meeting recording, depending only on the instruction:
Transcribe this recording and label each speaker.
Translate this audio into English.
What decisions were made in this meeting?
To demonstrate how the model copes with messy turns, the release points it at a classic scene from the 1940 screwball comedy His Girl Friday, a film known for rapid-fire, heavily overlapping dialogue. In the captioned scene, Nemotron 3.5 Transcribe keeps speaker labels attached even when lines collide.
For unfamiliar vocabulary, exhaust prompting before training. In a healthcare setting the pattern looks like this:
Transcribe this medical discussion in the original language. Possible terms: HbA1c, metformin. Use these terms only when supported by the audio. Preserve standard medical spelling and write numbers in conventional written form.
The model card ships recommended presets, including reasoning behaviour for audio questions, plus the full prompt guide and the task-by-language matrix. The caveat every speech model shares still applies: spot-check names, speaker changes and generated answers against the recording.
Word-level timestamps enable a simple downstream pattern. In a classroom demo, Agora used them: the company's real-time voice and video platform powers live conversations in apps, and with Nemotron 3.5 Transcribe a recorded class becomes a transcript shown alongside the replay, so students see what was said and when. Agora's blog walks through the build.
Leaderboard placement, read task by task
Two signals matter for tool selection: Transcribe leads open-weight models on content accuracy, and it tops two speaker-attribution benchmarks outright for speaker identity.
Hugging Face Open ASR Leaderboard
Public test sets are scored by word error rate (WER), and the leaderboard has three tracks:
- English: 5.33% average WER, first among open-weight models (Figure 1).
- Multilingual: 4.62% mean WER across seven languages, the lowest among evaluated open-weight models in the model card's Open ASR comparison.
- Long-form: 10.98% mean WER, also the lowest in that comparison.
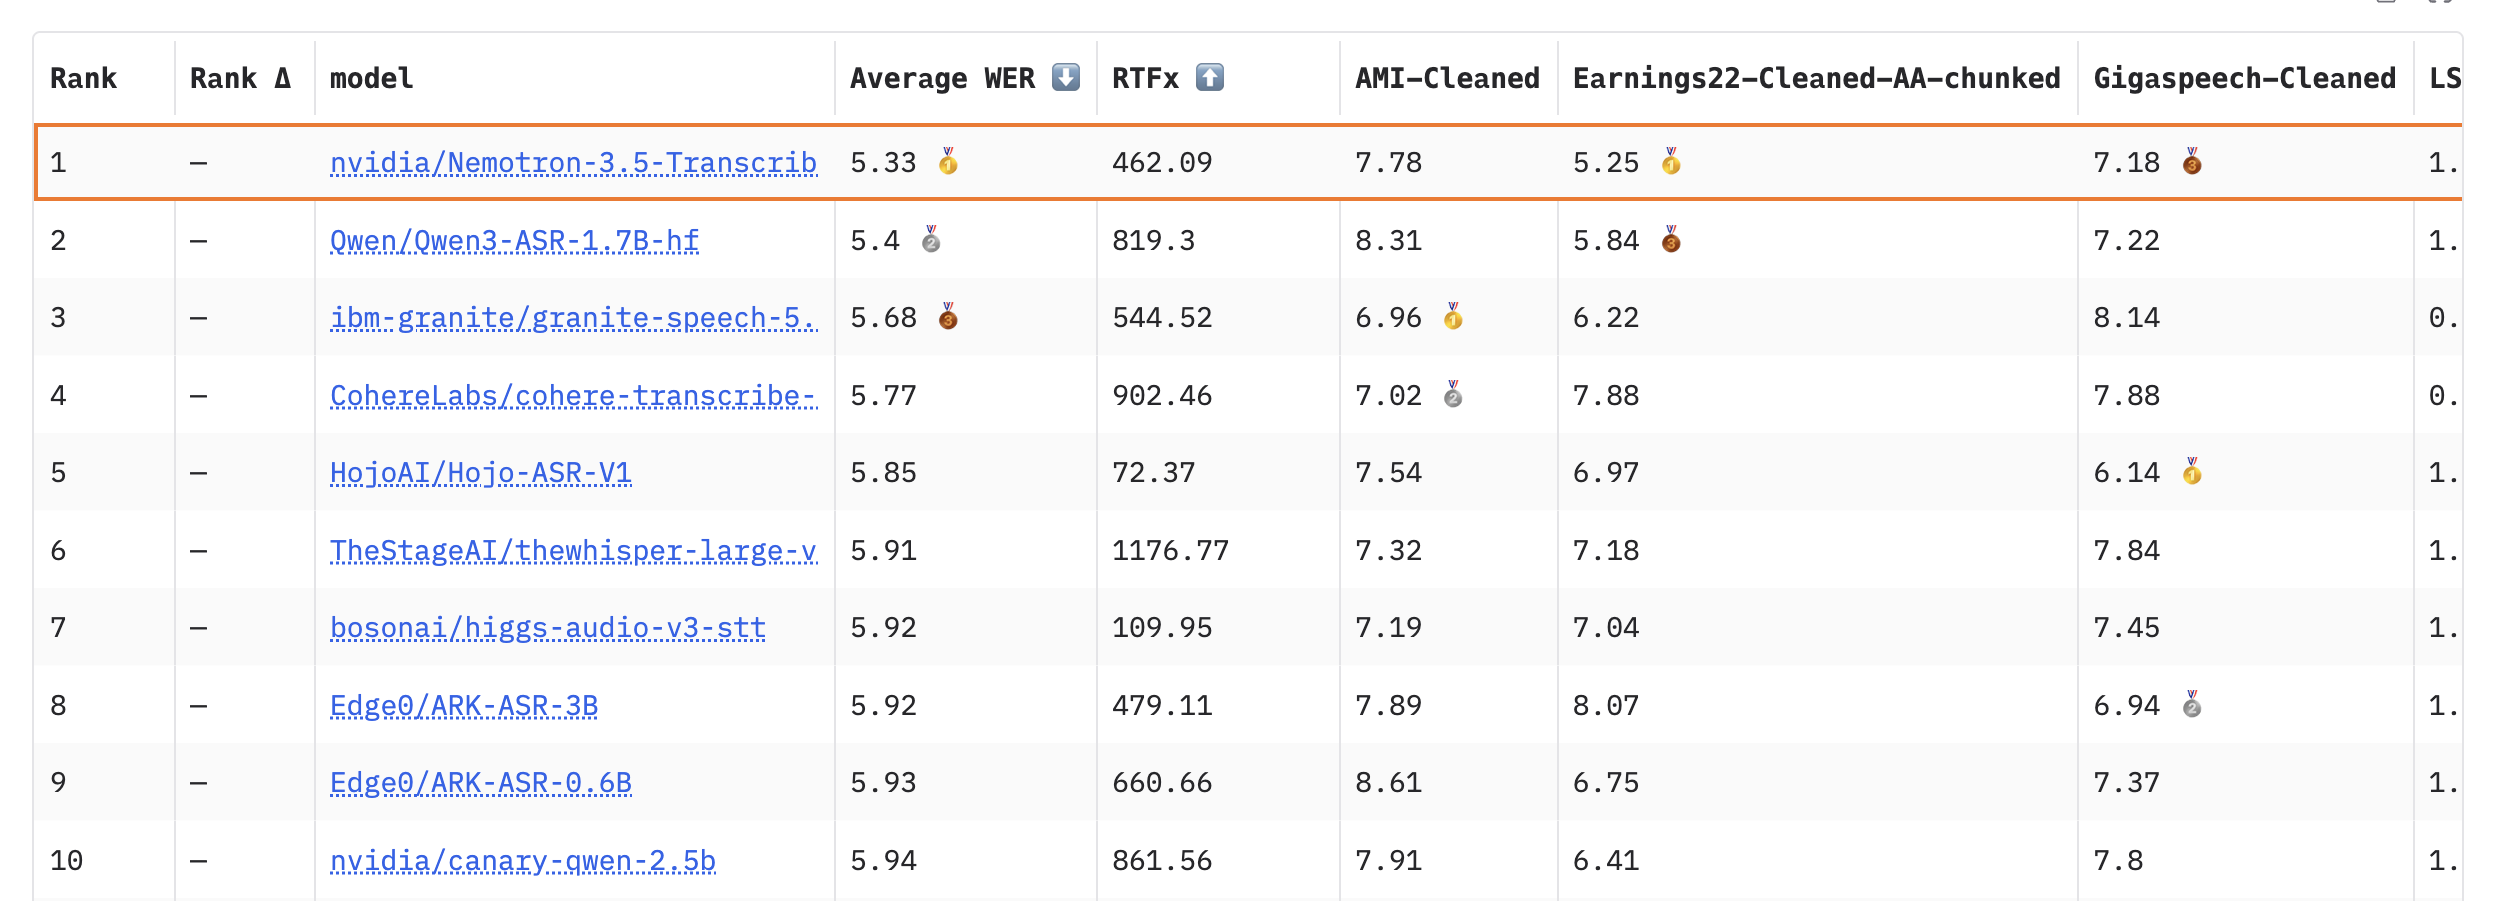
Figure 1. With API models excluded, Nemotron 3.5 Transcribe ranks first among open-weight models on the Hugging Face Open ASR Leaderboard (English) at 5.33% average WER; lower WER means fewer transcription errors.
Artificial Analysis Speech-to-Text Leaderboard
Artificial Analysis ranks speech-to-text models independently with AA-WER, its word error rate index. At 2.8% AA-WER, Nemotron 3.5 Transcribe ties for first among open-weight models while carrying about 4B active parameters, versus 24B for the model it ties. On AA-AgentTalk — the held-out voice-agent speech set that makes up 50% of the AA-WER index — it scores 1.8% WER against 2.3% for the next-best open-weight model.
The efficiency story is architectural: a speech encoder paired with a hybrid Mamba–Transformer mixture-of-experts language model, so only about 4B of 30B parameters are active per token. That puts it on Artificial Analysis's open-weight Pareto frontier of accuracy versus active parameters, and on the all-model chart it ranks ahead of several widely used proprietary speech APIs.
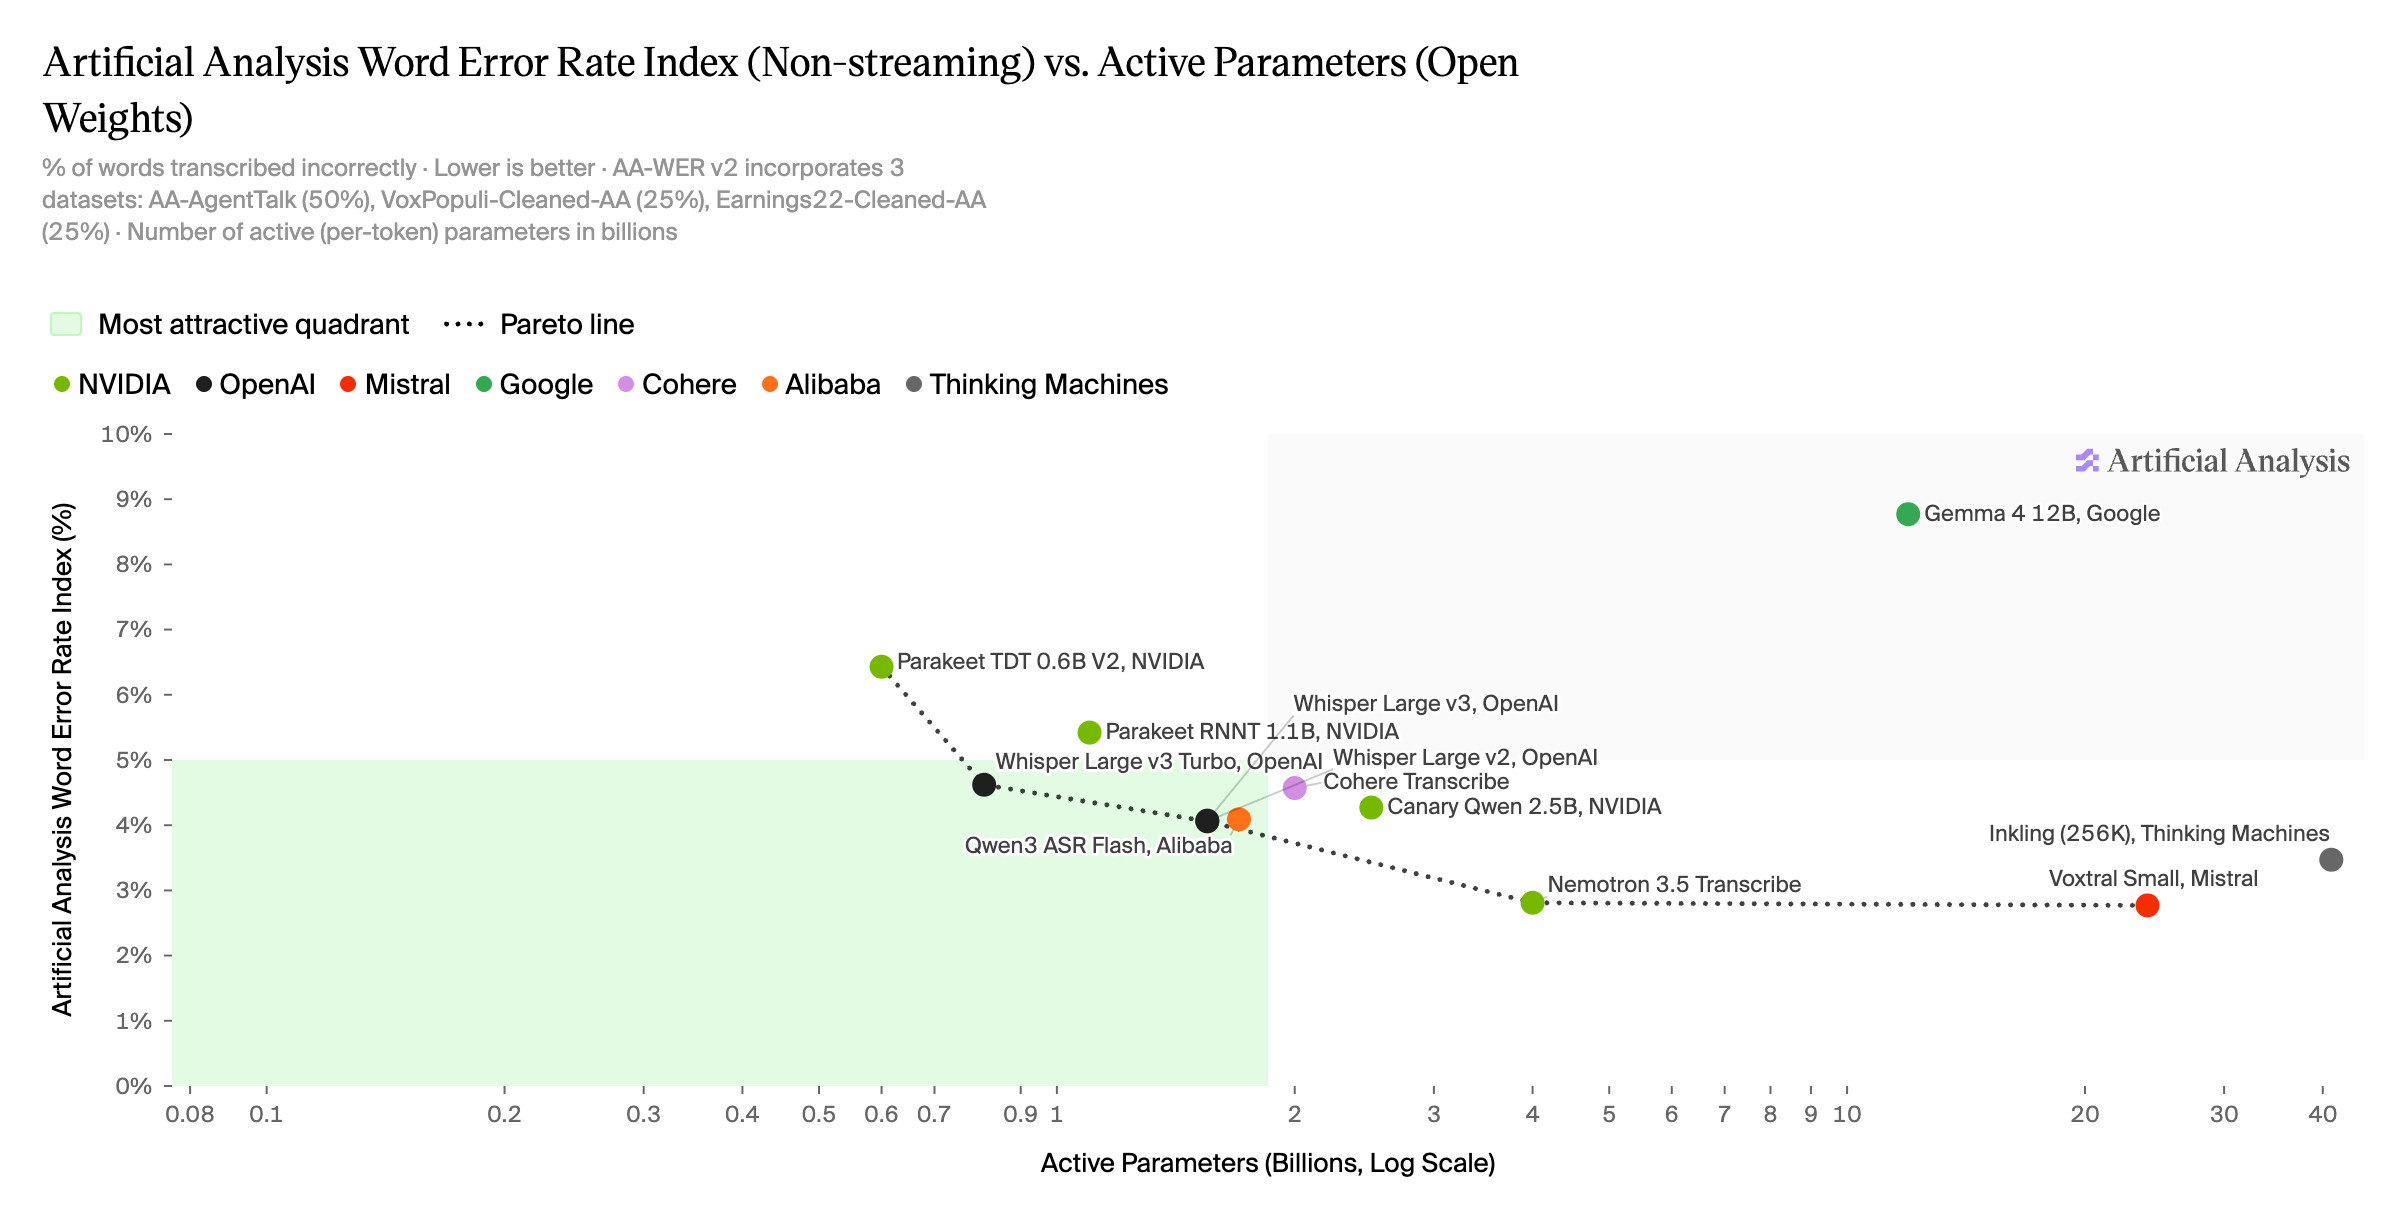
Figure 2. About one-sixth the active parameters supports leading AA accuracy: Nemotron 3.5 Transcribe achieves 2.80% AA-WER with approximately 4B active parameters.
Speaker attribution across languages and overlap
Because Sortformer speaker cues reach the language model together with the acoustic features, Transcribe can tag each turn during generation rather than relying on a later step to attach speakers to words.
David AI DAI-ASR-I18N Leaderboard
On the David AI DAI-ASR-I18N Leaderboard, Transcribe ranks first among evaluated open-weight models on the combined transcription-and-speaker-attribution track and second overall. On the benchmark's diarization track, which scores who spoke when across the 21-language set, it posts the lowest diarization error rate of the 14 systems tested, slightly ahead of NVIDIA's dedicated Nemotron 3 Diarization model.
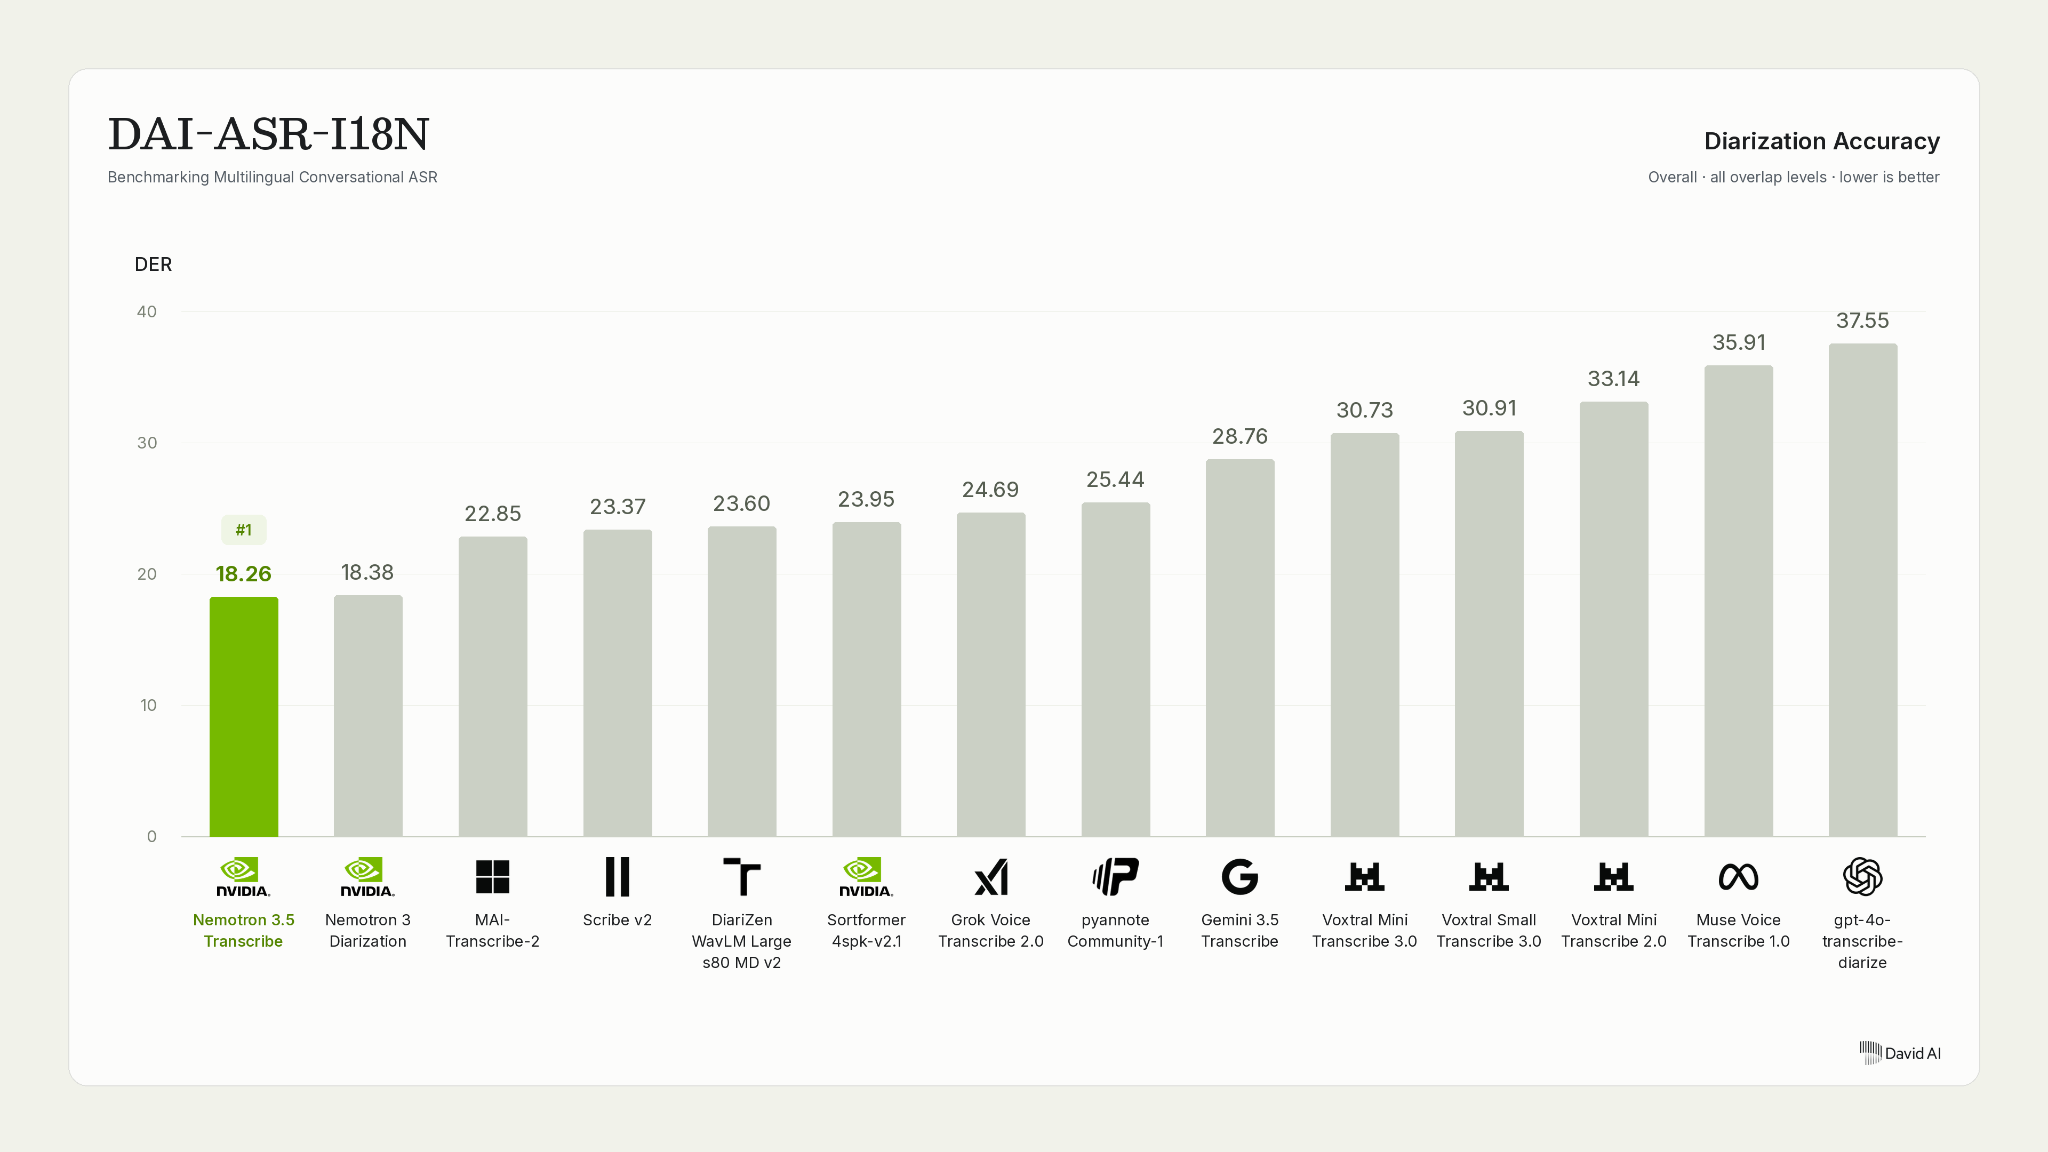
Figure 3. The top two spots on David AI's multilingual diarization leaderboard belong to NVIDIA models: Nemotron 3.5 Transcribe posts the lowest overall diarization error rate (DER), 18.26% across 21 languages, followed by Nemotron 3 Diarization at 18.38%. DER measures speaker-time errors; lower is better.
VoiceArena Diarization-Bench
On VoiceArena Diarization-Bench's English full-session benchmark, Transcribe posts the lowest concatenated minimum-permutation WER (cpWER) of the 14-system field and ranks first in both in-person and online settings. It also drops the fewest words: deletions are 8.32% of reference words, versus a median of about 31%.
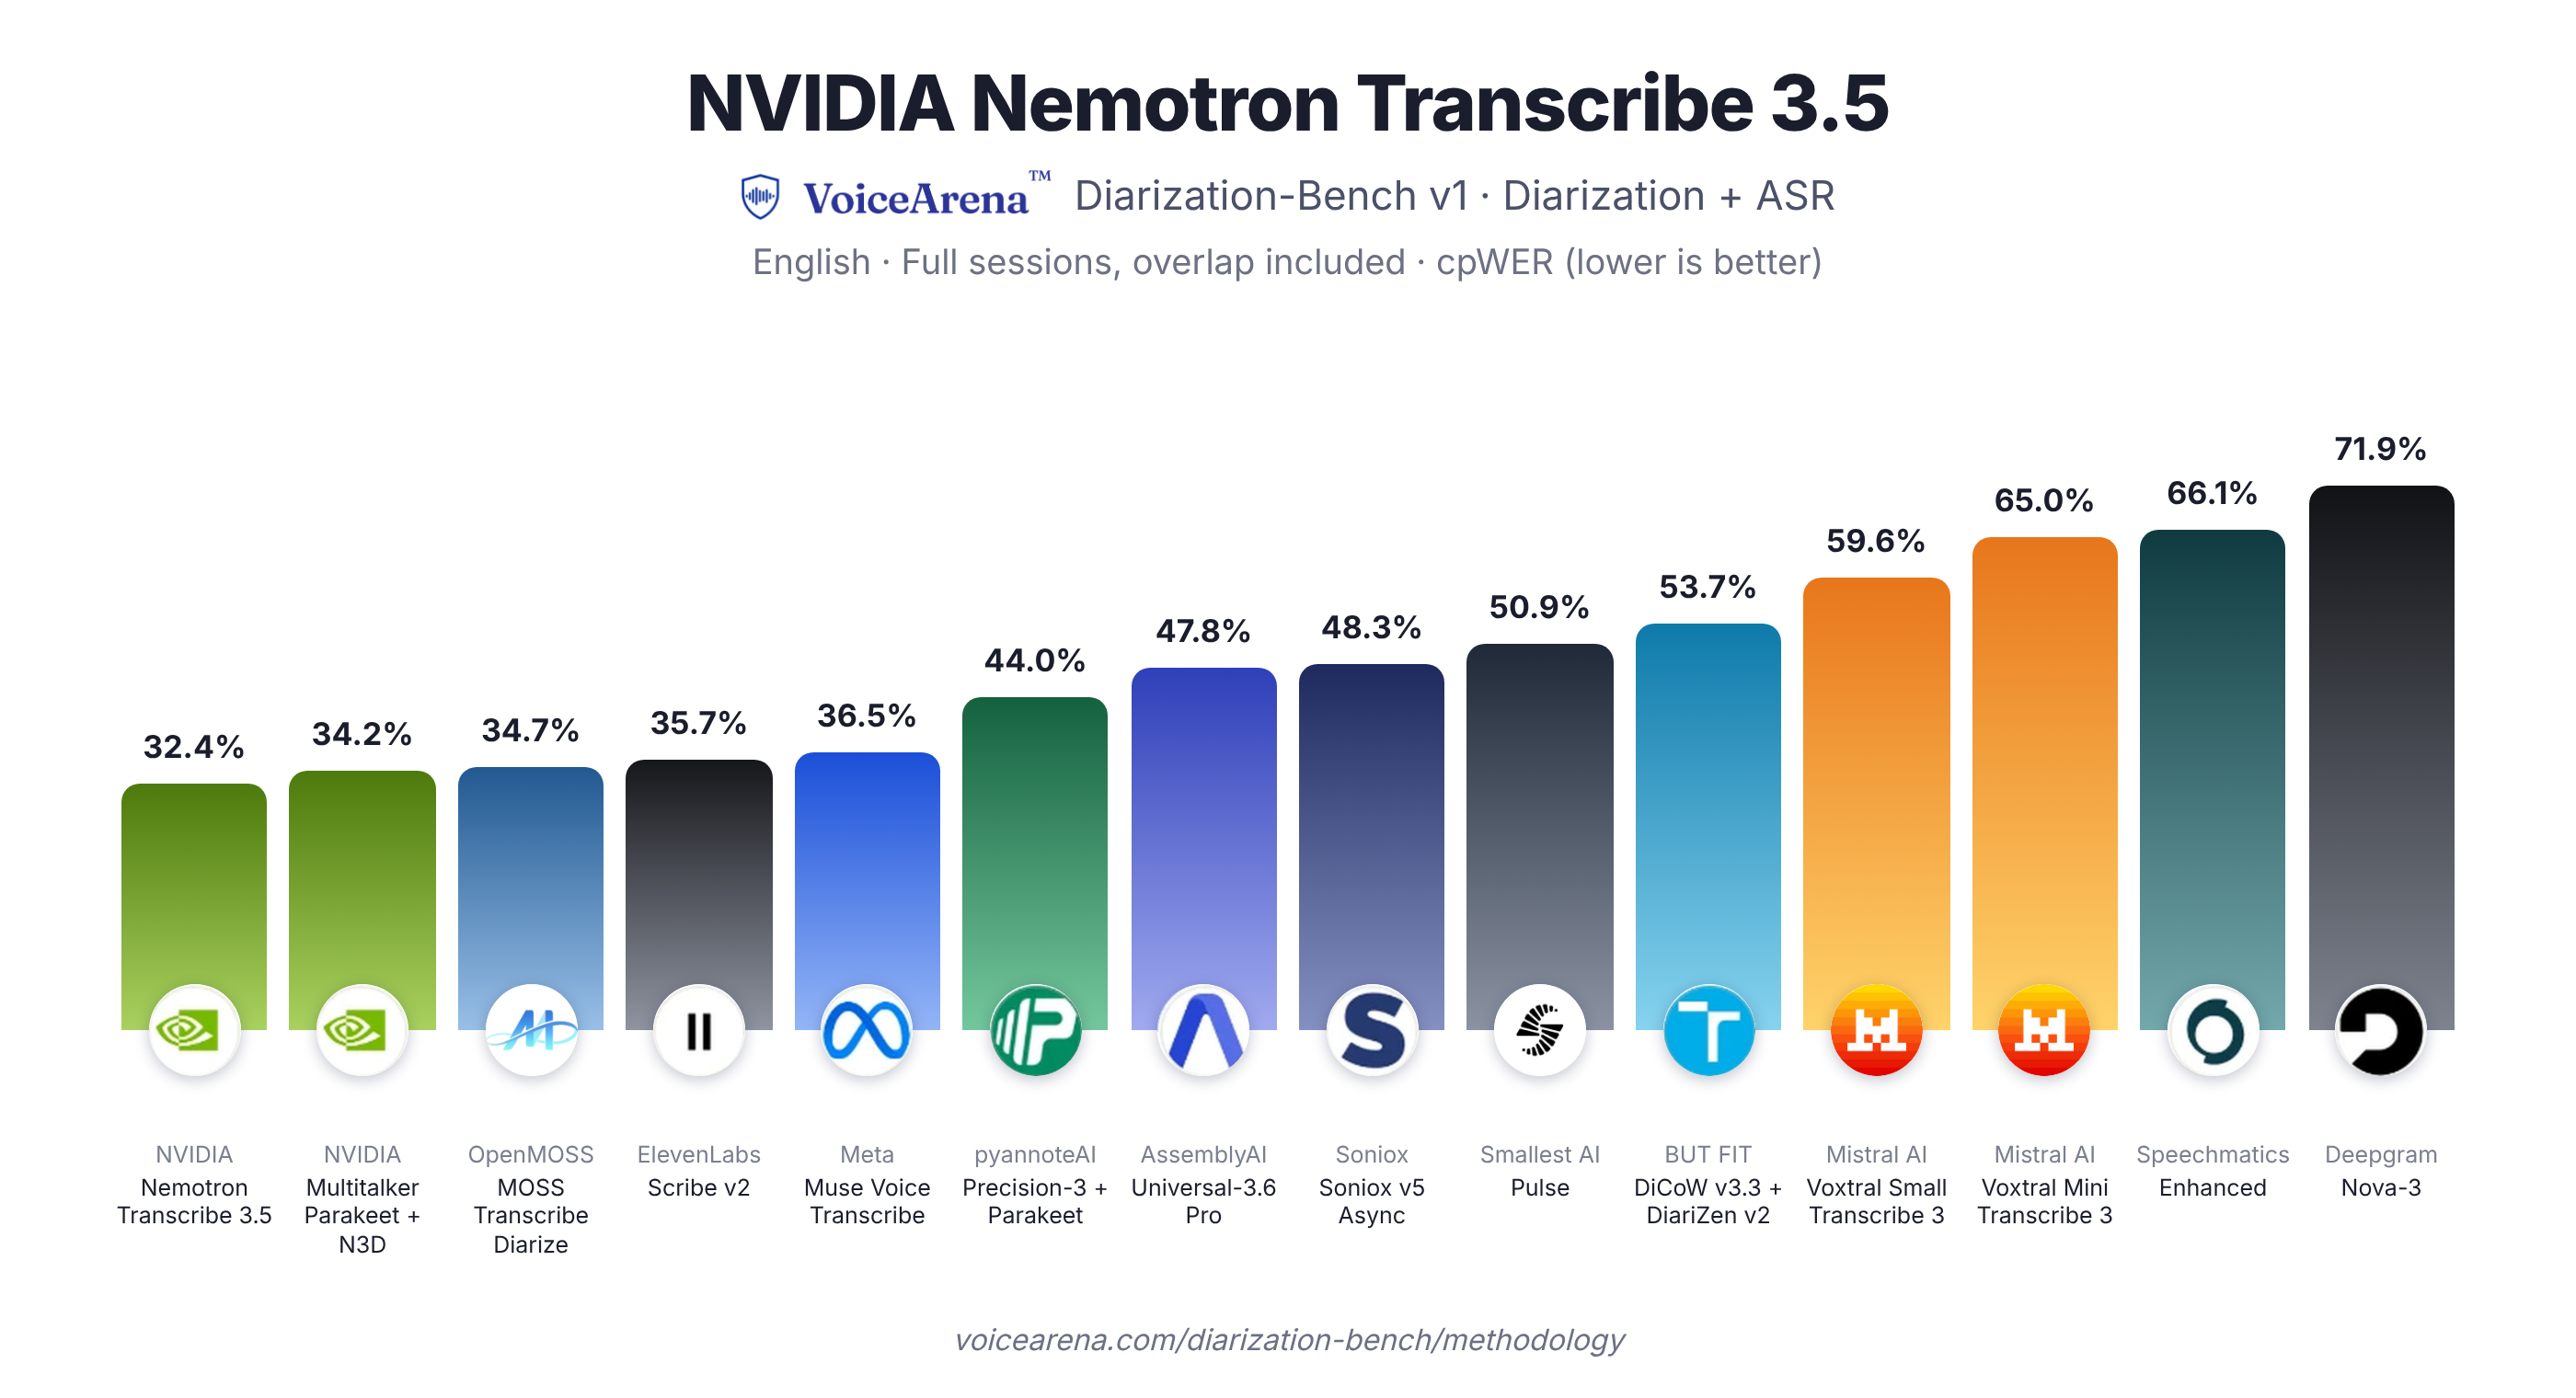
Figure 4. In VoiceArena's 14-system comparison, NVIDIA models hold the top two spots: Nemotron 3.5 Transcribe leads at 32.4% cpWER, followed by NVIDIA Multitalker Parakeet with Nemotron 3 Diarization at 34.2%. Diarization-Bench v1 covers English full sessions, overlapping speech and 2–8 speakers. cpWER counts word errors after matching speaker labels; lower is better.
Other evaluations, plus throughput
Independent checks line up: in Ocular AI's Converse-STT evaluation, Transcribe is ranked the top open model, and Josh Talks' Voice of India leaderboard reports its results across Indian languages — useful evidence if your user base is India-heavy.
Throughput decides whether a backlog job is affordable. In vendor benchmarking, Transcribe processed 100 hours of audio in under three minutes on one NVIDIA RTX PRO 6000 Blackwell Server Edition GPU using the forthcoming NVFP4 quantized version, measured on 30-second clips at high concurrency. Re-measure that on your own clip lengths before sizing a cluster.
Headline numbers side by side
| Benchmark | Reported result | Scope to keep in mind |
|---|---|---|
| Hugging Face Open ASR Leaderboard | 5.33% average WER, first among open-weight models | three tracks: English, multilingual 4.62% across seven languages, long-form 10.98% |
| Artificial Analysis Speech-to-Text Leaderboard | 2.8% AA-WER, tied first among open-weight models | about 4B active parameters versus 24B for the model it ties; 1.8% on AA-AgentTalk versus 2.3% next-best |
| David AI DAI-ASR-I18N Leaderboard | Lowest DER of 14 systems, 18.26% across 21 languages | Nemotron 3 Diarization follows at 18.38% |
| VoiceArena Diarization-Bench | 32.4% cpWER, first in in-person and online settings | NVIDIA Multitalker Parakeet with Nemotron 3 Diarization at 34.2%; deletions 8.32% versus a median of about 31% |
Granary v2: the open curation pipeline you can rerun
A promptable speech model needs training data with unambiguous formatting targets, and that is the role of Granary v2. It is part of the Nemotron speech collection on Hugging Face and ModelScope, and its reusable pipeline was built with NVIDIA NeMo Curator to prepare the multilingual speech used in Nemotron 3.5 Transcribe's training, producing aligned transcript variants, task labels and inspectable quality metadata. The public manifest covers 463,062 hours across 48 languages and 16 source corpora, up from 25 languages in Granary v1. Those figures describe the dataset release, not Transcribe's full training mixture or its sampling weights.
For each recording the pipeline generates three transcript forms, matching the verbatim and clean styles you can request from Transcribe with a prompt. Beyond transcription it also produces short audio captions, code-switching restoration of loanwords, speech-grounded Q&A pairs, contextual ASR biasing terms, and translations with automatic quality scores.
| Training target | Illustrative transcript |
|---|---|
| Text-normalized, verbatim | I paid, uh, twenty-five euros. |
| Inverse text normalization, with disfluencies | I paid, uh, €25. |
| Inverse text normalization, without disfluencies | I paid €25. |
Table 1. Granary v2 training targets for the same utterance.
Work is organized into four reusable stages:
- Audio Preparation (Metadata): raw or long-form audio is segmented, speakers are tracked across the full recording, and acoustic events and language are tagged. Because Granary v2's sources were already segmented, this release skipped the stage.
- Transcription (ASR): each language is routed to primary and recovery ASR models, falling back when the primary fails a hallucination check. Human reference transcripts preserve trusted spellings while spoken forms and disfluencies are added.
- Task Label Generation (Text): transcript variants are derived, then character rate, hallucination patterns and model-versus-human-reference agreement are checked. Only accepted records receive contextual-ASR terms and translations.
- High Fidelity (HiFi): noisy, clipped or multi-speaker segments are filtered out, keeping a smaller set of high-quality recordings for uses beyond ASR. On VoxPopuli, it reduced 354k hours to 111k hours across 22 European languages.
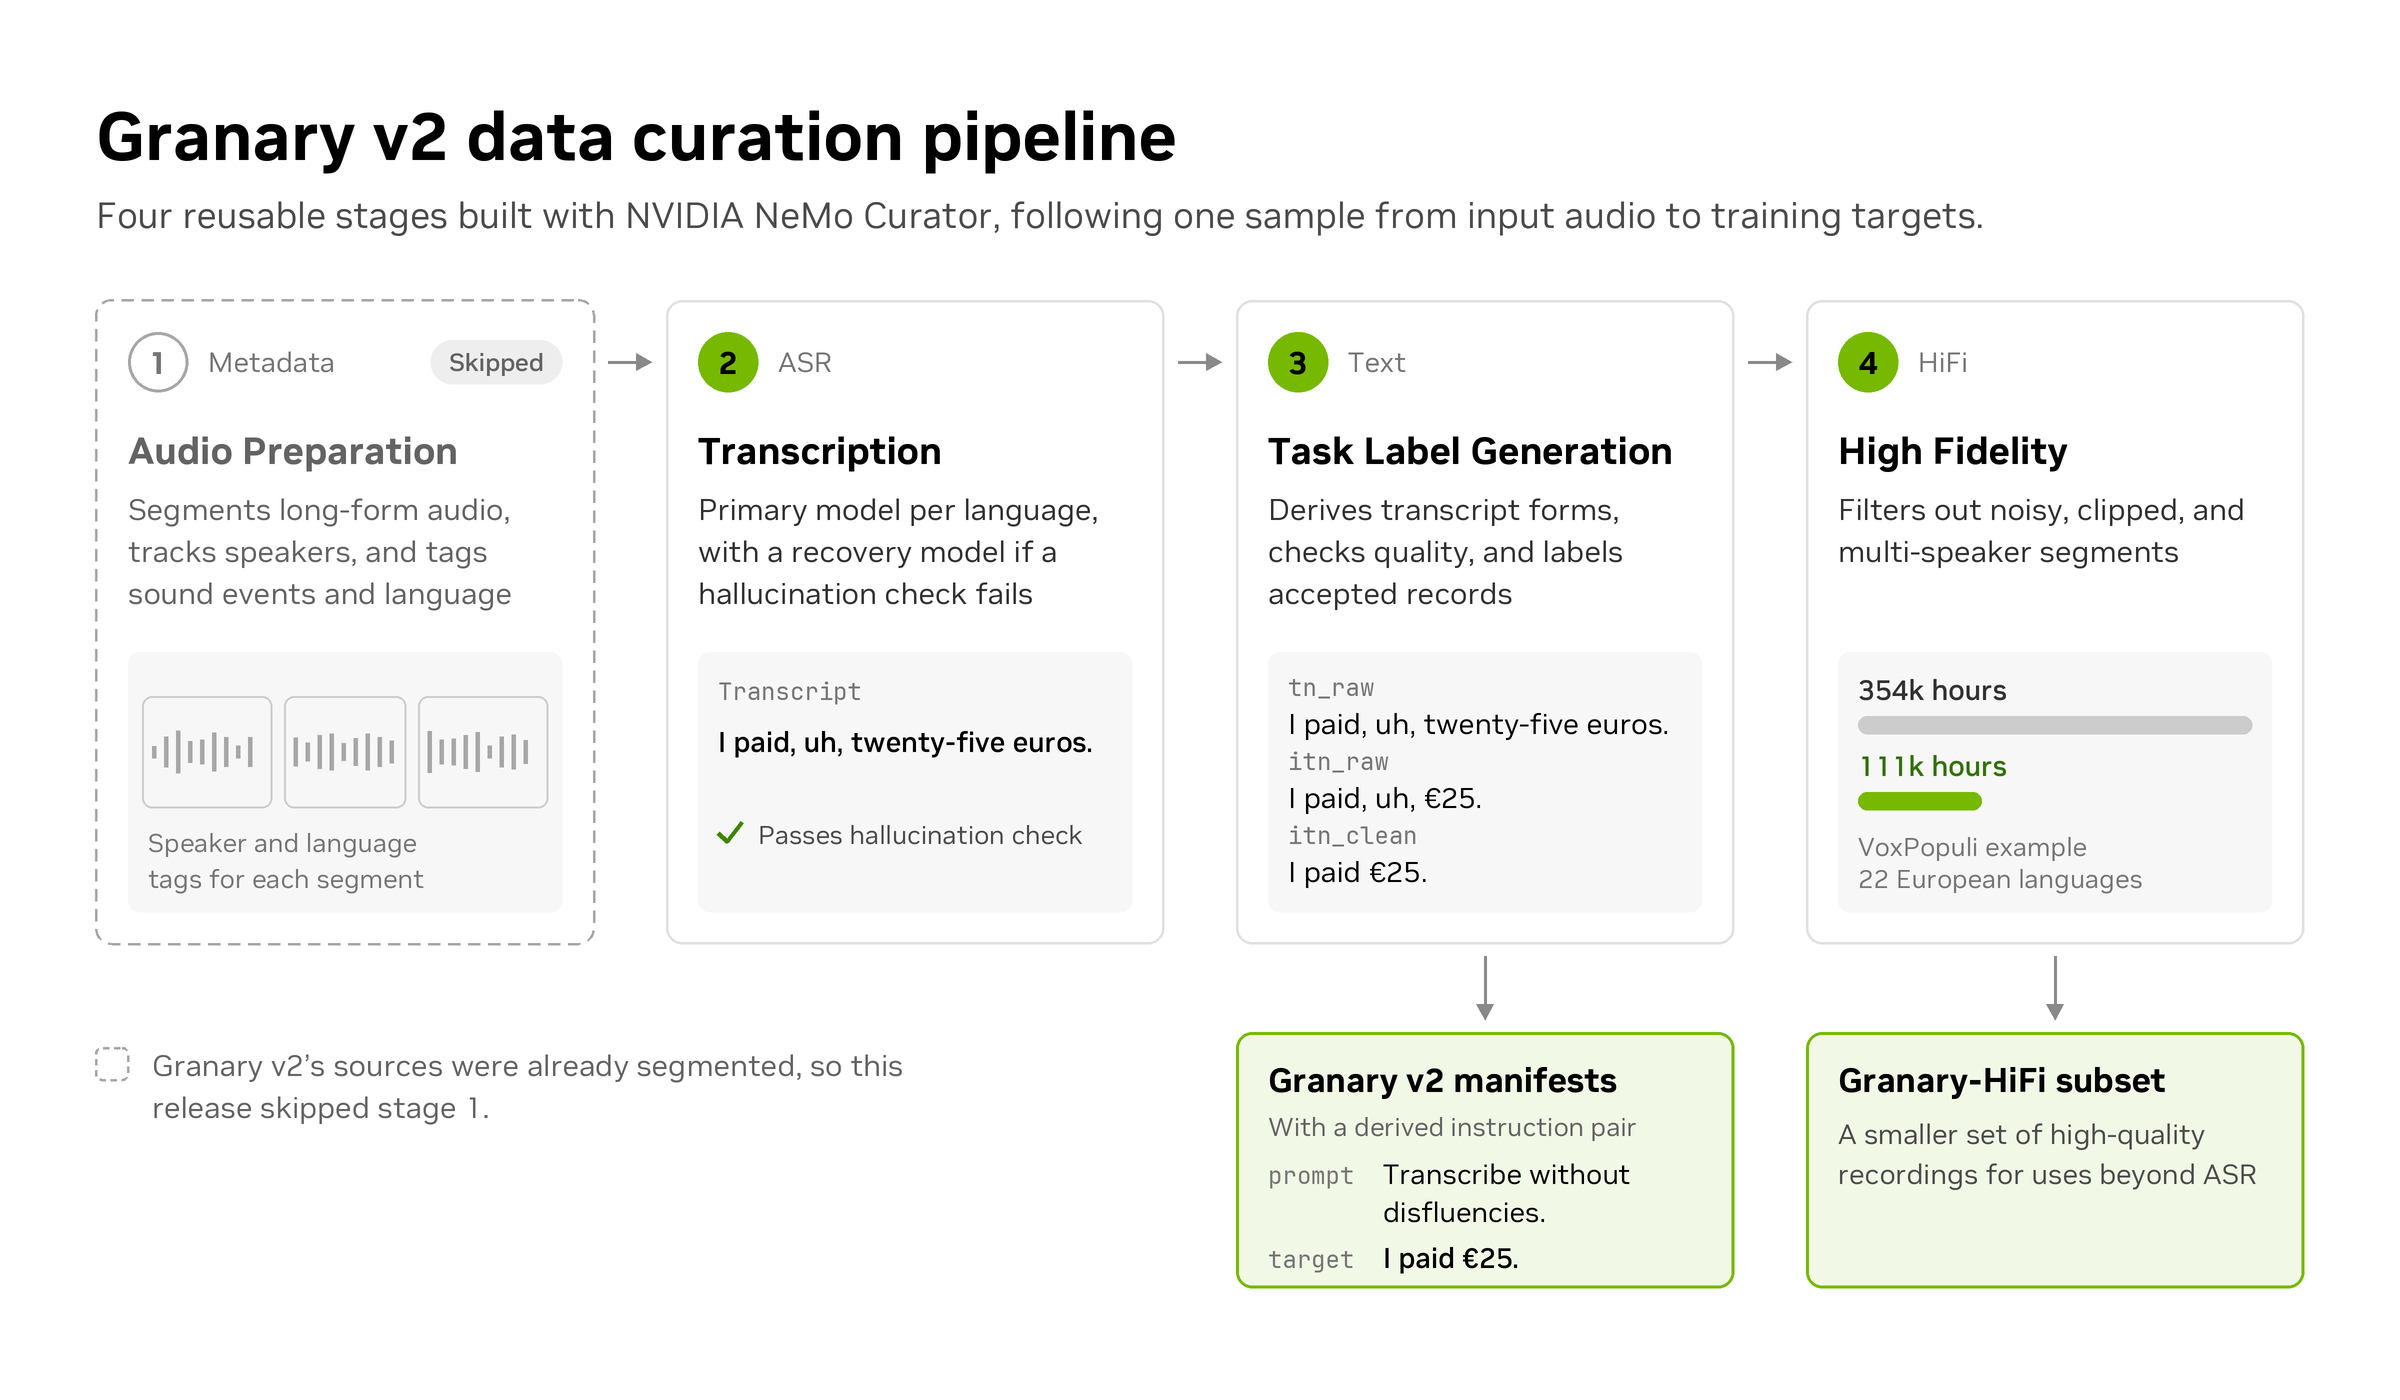
Figure 6. The Granary v2 data curation pipeline follows one sample from raw audio through the Metadata, ASR, and Text stages to a training example.
Developers can run the NeMo Curator pipeline with Ray and NVIDIA Dynamo backends over their own recordings or authorized public corpora, or build directly on the Granary v2 public manifests. The manifests include the three transcript forms as tn_raw, itn_raw and itn_clean, the labels described above, entity hints, derived instruction pairs, provenance and a per-record quality flag. Download source audio separately under each corpus's original license, and follow the release's published terms.
Deployment options compared
| Route | Status today | Best fit |
|---|---|---|
| Managed demo | Hugging Face demo and ModelScope Studios | Quick prompting and quality evaluation with no infrastructure |
| Self-hosted | Serve the checkpoint now with the vLLM deployment guide | Data-residency needs, private audio, predictable batch cost |
| Local and edge | NeMo-Speech.cpp plus quantized versions coming soon | Offline workflows on RTX Spark, DGX Spark, Jetson AGX Thor |
| Hosted endpoints | Baseten, DeepInfra or Simplismart | Teams skipping self-hosting entirely |
| Data-side tooling | Granary v2 Manifests and NeMo Curator pipeline | Building your own formatted targets and labels |
Domain adaptation: the medical case study, step by step
A development-set prompt should pin down language, script and transcript format. In the case study, simply naming English and the Latin alphabet cut full-benchmark WER from 30.8% to 23.8%. For the domain errors that survive that step, the NeMo Speech fine-tuning workflow pairs representative speech with explicit written targets.
The demonstration uses Eka Care's open benchmark of recordings from Indian doctors and medical students — 3,619 clips with no designated training split. Adaptation data was built from generated medical text and public medicine catalogs, then combined approximately 153 hours of synthetic speech, 29 hours of accented English from Common Voice, and 63 hours of medical recordings from MultiMed.
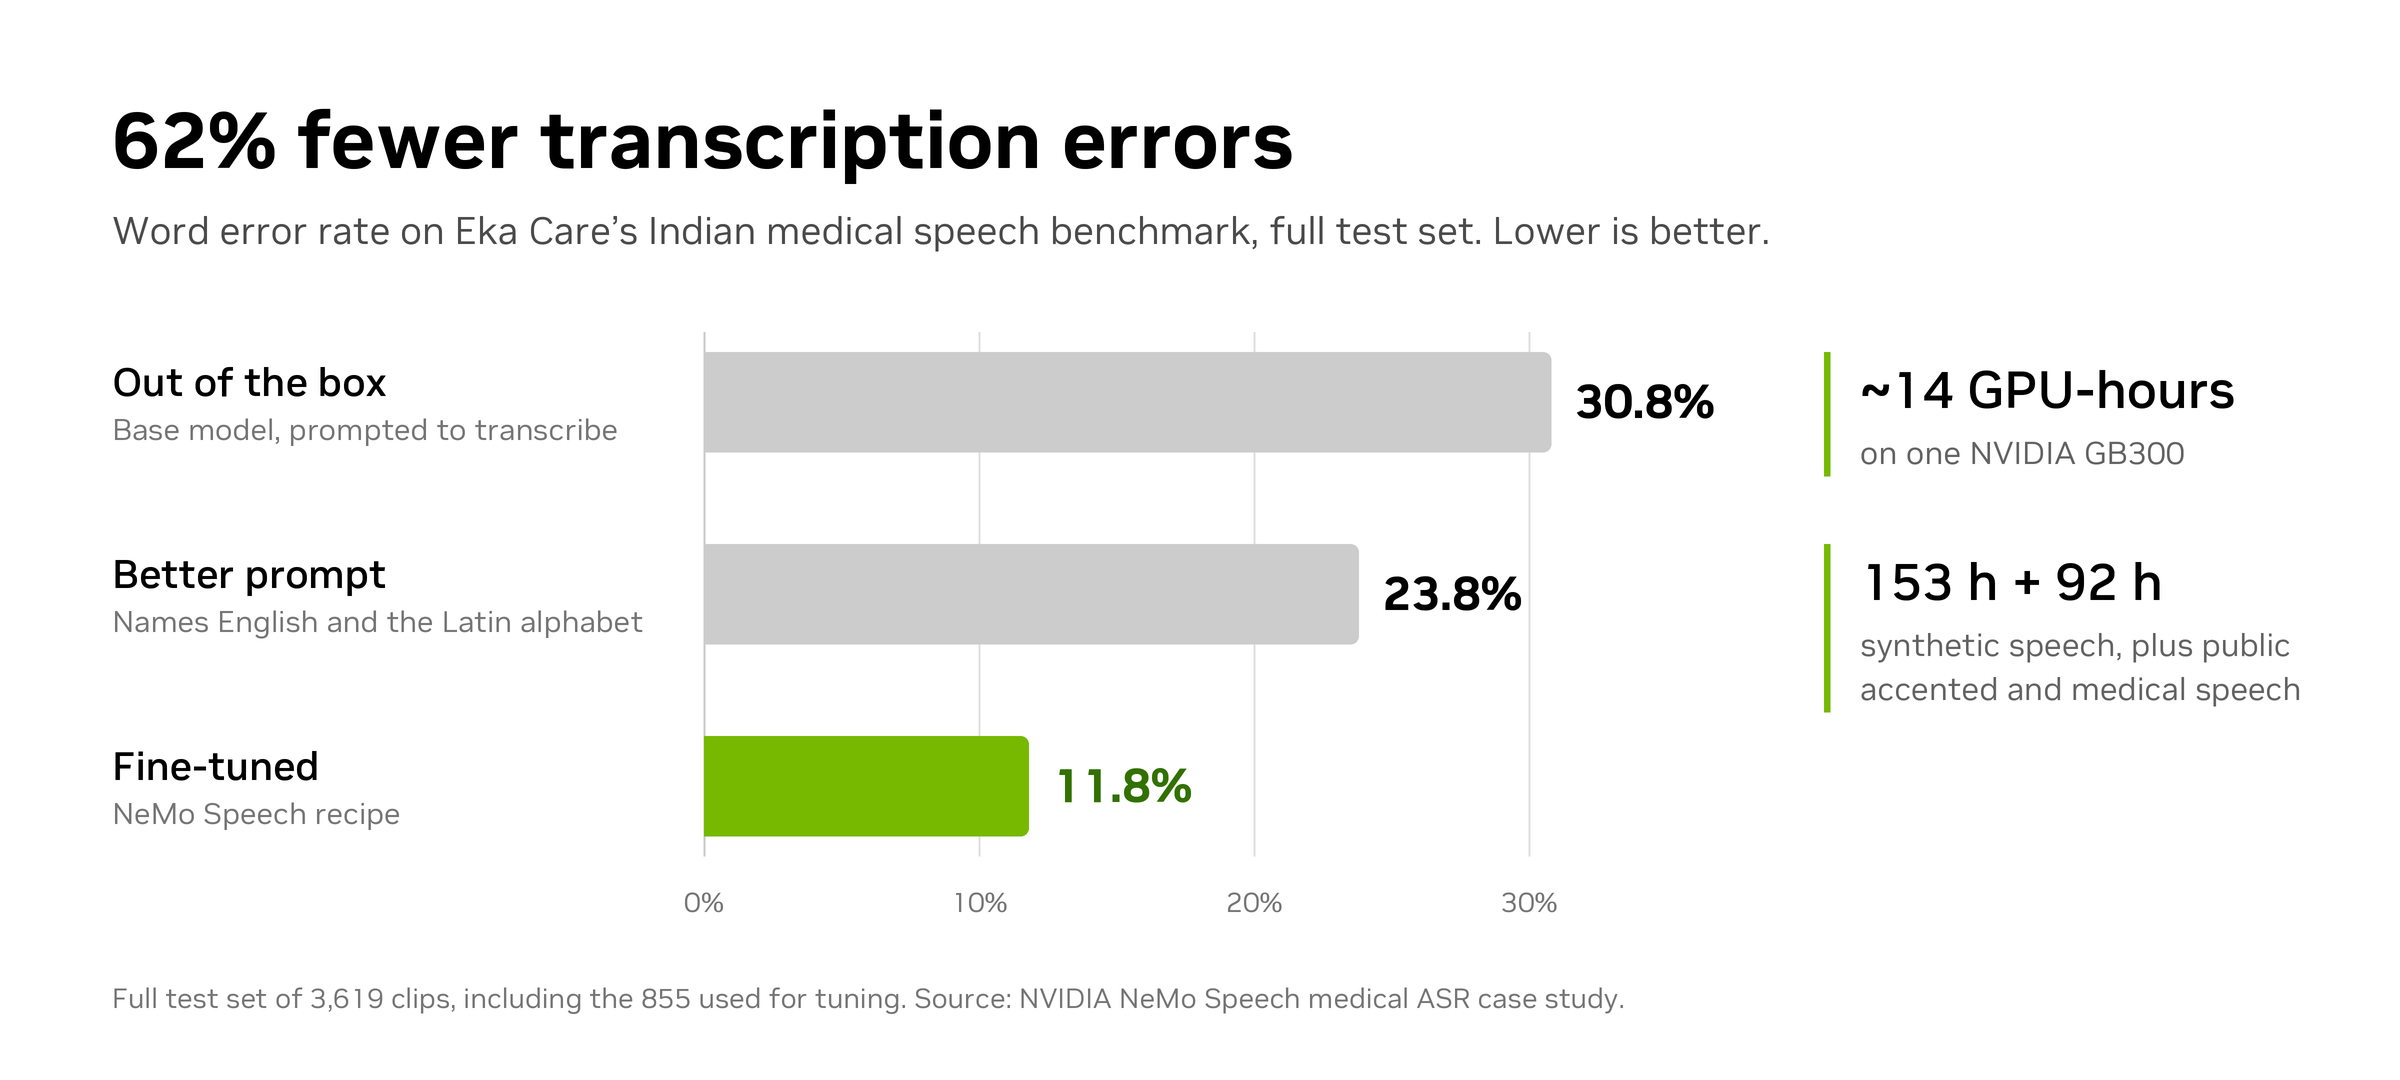
Figure 7. On Eka Care's Indian medical speech benchmark full test set, a better prompt cuts WER from 30.8% to 23.8%, and fine-tuning brings it to 11.8%, about 62% fewer transcription errors than the model out of the box. The full set includes the 855 tuning clips used to choose the prompt and checkpoints; the held-out results are the cleaner test.
Separate the written target from the spoken form
Synthetic generation keeps the two apart: "HbA1c" is the written label, while "H B A one C" is what the synthesizer is asked to speak. Multiple TTS voices widen the audio, real recordings contribute accents and recording conditions, and training text is filtered for exact matches and shared eight-word sequences with benchmark references.
As in Granary v2's explicit targets, training examples vary digits, unit spacing, company-name expansion and brand-name hyphens, with instructions specifying the required convention. Some prompts include term lists with near-miss distractors so the model learns to apply a spelling only when the audio supports it. The final system uses one fixed convention prompt and one model pass, without retrieval or transcript post-processing.
Training configuration
LoRA adapts the language model while the recipe trains the speech encoder and projection. Two runs use different data mixtures; after adapter merging, selected checkpoints are uniformly averaged into one final model. Checkpoint selection relies on decoded development-set results rather than training loss alone. The full adaptation, from text generation through evaluation, took about 14 GPU-hours on one NVIDIA GB300.
Results measured on held-out speakers
Splitting the benchmark by speaker produces 855 tuning clips, used to choose the prompt and checkpoints, and 2,764 held-out clips decoded once per final system. With Eka Care's KARMA scoring pipeline, fine-tuning cuts held-out WER from 22.44% for the best-prompt baseline to 12.17%, a 45.8% relative reduction and the clearest evidence that the gains generalize to new speakers.
| Metric (held-out speakers) | Best prompt | Fine-tuned |
|---|---|---|
| WER | 22.44% | 12.17% |
| Keyword WER | 9.2% | 6.5% |
| Semantic WER | 10.0% | 7.6% |
On the same held-out speakers and scorer, the adapted model's 12.17% WER also beats an open medical-specialist model (13.79%) and a widely used general-purpose ASR model (14.92%). General English pays a small price: LibriSpeech test-clean WER rises slightly, from 1.54% to 1.69%. Exact matches for brand-name drugs and diagnostics are still led by the medical specialist, and the study points to real recordings of clinicians saying brand names as the next step. For your own domain, keep at least 100 real, labeled clips for checkpoint selection, and evaluate the entity types your application depends on alongside general-speech retention.
Commands to reproduce each step are included in the case study. The fine-tuning tutorials cover recipes, resource requirements and tools for training, export and evaluation, including new-language and code-switching ASR, and the accompanying agent skill lets a coding agent run the workflow from baseline selection and data checks through training validation, adapter merging and evaluation. For specialized multimodal applications, ModelScope also enables developers to fine-tune Nemotron 3.5 Transcribe through its ms-swift framework.
Getting started in five steps
- Evaluate before installing: try Nemotron 3.5 Transcribe in the Hugging Face demo or on ModelScope Studios with one real recording, not a clean sample.
- Serve it your way: download the checkpoint from Hugging Face or ModelScope and follow the vLLM deployment guide, or skip self-hosting with a hosted endpoint from Baseten, DeepInfra or Simplismart.
- Write the convention prompt: fix language, script, digit and unit handling, and entity spellings, then run the three prompt styles above against the same audio.
- Score before you train: split your test set by speaker, record WER and keyword errors, and separate what prompting already solves from what needs adaptation.
- Adapt if domain errors persist: start from the Granary v2 Manifests on Hugging Face or ModelScope and the medical ASR case study, or let a coding agent drive the fine-tuning agent skill; ModelScope's ms-swift path covers the same adaptation for multimodal setups.
FAQ
Do I need to fine-tune to get usable output?
No. Prompting alone moved full-benchmark WER from 30.8% to 23.8% in the case study; fine-tuning took it to 11.8%. Try the model card presets and a convention prompt first.
Is this a live-streaming transcriber?
No. Transcribe is built for recorded audio, up to an hour long, with up to eight speakers labeled.
Does every supported language get every task?
No. Language support differs by task: 40 languages for transcription, 31 for translation to or from English, 13 for speaker attribution, and audio question answering is trained in English.
Can I run it on my own machine?
Serving today is via vLLM; quantized versions plus NeMo-Speech.cpp are coming soon for local use on RTX Spark, DGX Spark or Jetson AGX Thor, and larger deployments on Blackwell hardware.
Can I reuse Granary v2 data for my own model?
You can build on the public manifests or rerun the NeMo Curator pipeline with Ray and NVIDIA Dynamo backends, but source audio must be downloaded separately under each corpus's original license.
What does adaptation cost in time?
The reference medical adaptation took about 14 GPU-hours end to end on one NVIDIA GB300, using LoRA plus encoder and projection training.
Common misconceptions
- One leaderboard win means accuracy everywhere. Scores differ by track: 5.33% average WER in English, 4.62% across seven languages in the multilingual track, 10.98% on long-form.
- More active parameters must mean better results. The Artificial Analysis view shows leading accuracy with about 4B active parameters — roughly one-sixth of the tied model's 24B.
- Diarization is always a separate downstream tool. Here Sortformer cues reach the language model with the acoustic features, so turns are tagged during generation.
- A term list guarantees correct spellings. The recommended prompt explicitly says to use terms only when supported by the audio; spot-checking is still required.
- Granary v2's 463,062 hours is the training set. It describes the dataset release across 48 languages and 16 source corpora, not Transcribe's full training mixture.
- Fine-tuning solves brand-name drugs. Exact matches for brand names and diagnostics remain with the medical specialist model for now.
Action recommendations for this week
- Pick one overlap-heavy recording and one long session, and run the three prompt styles against them to set your baseline expectation.
- Document your written conventions — digits, currency, units, drug or product names — as a reusable prompt instead of ad-hoc post-editing.
- Decide where audio is processed before you pilot: self-host with vLLM for residency, or a hosted endpoint via Baseten, DeepInfra or Simplismart.
- Reserve at least 100 real, labeled clips per domain you care about, and hold out by speaker so results stay honest.
- Add a spot-check step to your workflow for names, speaker changes and answers generated by audio question answering.
- Re-check the roadmap for quantized builds and NeMo-Speech.cpp if edge or offline execution is on your planning horizon.
Resources worth bookmarking
Checkpoints and interactive demos for Nemotron 3.5 Transcribe live on Hugging Face and ModelScope; the Granary v2 Manifests and High Fidelity Subset are on the same two hubs. Code and guides sit in the NVIDIA NeMo Speech GitHub, the NeMo Curator Granary v2 Pipeline, the vLLM Deployment Guide, the Speech Fine-Tuning Guide and the Fine-Tuning Agent Skill. Implementation write-ups come from partner blogs by Agora, Inflection AI, VoiceArena, Simplismart and DeepInfra, and local AI coverage extends to NVIDIA RTX PCs, laptops and DGX Spark.
Bottom line
If your backlog is recorded audio rather than live streams, this release is the rare speech model that reduces tool count instead of adding another box to the pipeline: one checkpoint for transcription, translation, speaker labels and audio Q&A, public prompts and public training targets, and a measured adaptation path when your vocabulary refuses to cooperate. The practical next move is a small internal pilot on your own recordings, with a speaker-split holdout and a written convention prompt in place before anyone debates fine-tuning.
Reviewed by Sarah Chen for the MyTechDailyNews Software desk. Corrections and tips: hello@techdaily.com.